Sunk Cost
How long until a local LLM rig pays for itself?
About Sunk Cost
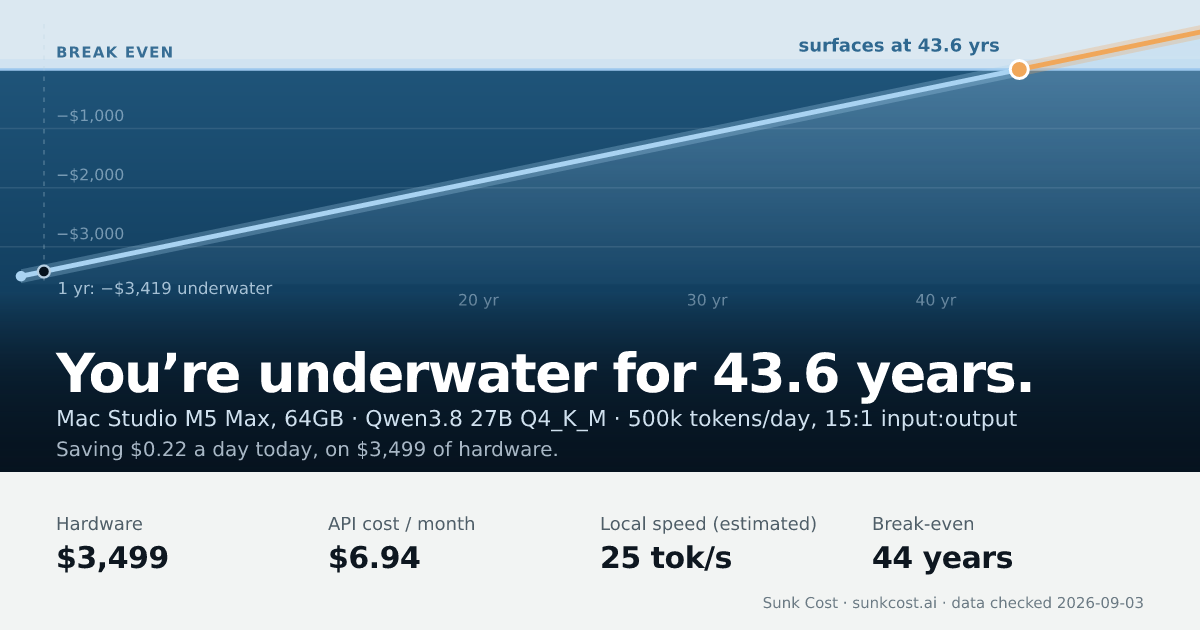
Which open models fit your machine, how fast they run, and how many tokens it takes to pay back the hardware against an API. Honest enough to say never.
In the maker’s words
I kept hearing "just buy a Mac and run models locally, it pays for itself" and wanted to check. Sunk Cost takes a machine, a model and how many tokens you use a day, and works out how long the hardware takes to pay back against renting the same model by the token. Obviously there are other reasons to buy your own hardware aside from just saving money on llms but this is just looking at it from a raw cost saving perspective. If you have any ideas on how I can make this more helpful lmk!
Where people found it
- Hacker NewsShow HN: Sunk Cost – How long until a local LLM rig pays for itself?47 points99 comments19 days ago
More sites like Sunk Cost
- Giving Opus 5.5 a simulated paint canvasstillwet.art
- AIHOT一个自己找热点、自己写日报的网站框架。把信源和精选标准换成你的,它就是你的行业热点站。
- Offrunmanage every coding agent from one workspace
- OpenDotsYour always-on AI coworkers that move between text, calls, and Slack.
- Pi podRun your pi coding agent in sandboxes on your own server
- HN.watchVideos of all Hacker News posts